Cognition reports up to 4.8x higher total token throughput for SWE-2 inference workloads versus a GB200 NVL72 baseline.
CoreWeave Inc. announced the availability of NVIDIA Vera Rubin NVL72 on CoreWeave, with Cognition as the first customer anywhere running production workloads on the system. Customers, like Cognition, run the system under the same operating model and tooling as their existing NVIDIA GB200 NVL72 and GB300 NVL72 fleets, with performance engineering from CoreWeave’s team. The news was shared during Fully Connected, CoreWeave’s AI cloud conference, which brings together more than 4,500 customers, partners, developers and AI leaders to share how they are building and running AI in production.
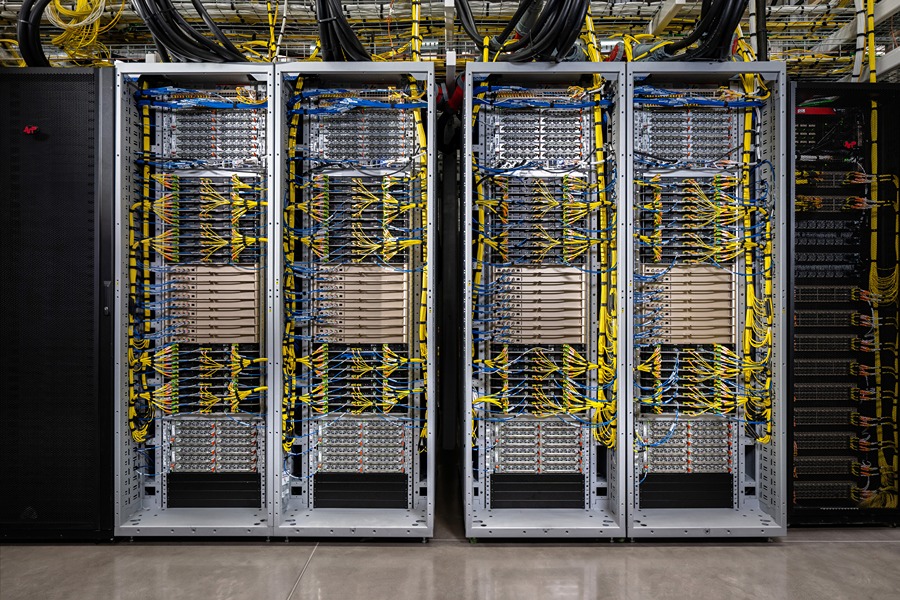
Cognition is the first customer in production with Vera Rubin NVL72
Cognition, the applied AI lab behind Devin, runs training, reinforcement learning and production inference for Devin on CoreWeave. The company scaled from bridge capacity to thousands of GPUs for training and inference in less than nine months. Cognition worked with CoreWeave to stand up a Vera Rubin NVL72 cluster in early September, and Cognition’s own engineers ran the first customer-executed Vera Rubin inference benchmark, measured against a GB200 NVL72 cluster baseline.
Cognition’s engineers benchmarked Vera Rubin
In independent benchmarks run on CoreWeave Cloud, Cognition measured a 4.8 times increase in total token throughput for its SWE-2 inference workloads on NVIDIA Vera Rubin NVL72 compared to a GB200 NVL72 baseline. Additionally, the team recorded a 3.8 times boost in output token throughput for reinforcement learning workloads. For Cognition, that translates to more concurrent Devin sessions per GPU, drastically accelerated research loops and lower cost per session, with no loss in generation speed.
Proven across every NVIDIA generation
The relationship between CoreWeave and NVIDIA dates to 2017, beginning with the NVIDIA Volta generation, which is still in commercial service today on CoreWeave Cloud, demonstrating the long useful life of NVIDIA compute and the value CoreWeave’s platform can continue to draw from it. CoreWeave’s full-stack software platform—including CoreWeave Kubernetes Service, SUNK, CoreWeave Mission Control, CoreWeave Sandboxes and serverless inference—gives customers a consistent way to deploy and manage workloads across GPU generations. Customers can match each workload to appropriate capacity, keep using existing infrastructure as needs evolve and adopt new NVIDIA architectures through a familiar operating environment.
CoreWeave, in collaboration with Dell Technologies, was among the first cloud providers to deploy Dell PowerRack systems featuring NVIDIA GB200 and GB300 NVL72, and is one of the first to deploy NVIDIA Vera Rubin. CoreWeave has also published the industry’s first measured silicon performance numbers on the platform, showing 10 times the token throughput per megawatt over NVIDIA GB200 NVL72 on the DeepSeek R1 reasoning model at matched interactivity.
CoreWeave consistently delivers industry-leading performance, demonstrated by record-breaking MLPerf benchmark resultsin inference and training and its position as the only AI cloud to earn the top Platinum ranking in SemiAnalysis ClusterMAX three times in a row.
For more information, visit coreweave.com.